Redefining Best Failed Payment Recovery Software Sep 2026
Vendor benchmarks for payment recovery software all tend to look the same: big recovery rate numbers, no control group, no way to know if your billing setup would have caught those payments anyway. But the proof problem is only half of it. The deeper issue is that "best" gets applied to tools as if all recovery gaps are identical, when retry timing, dunning logic, and account updater services are solving completely different failure modes. Knowing which one you actually need changes the whole evaluation.
TLDR:
- "Best" failed payment recovery software is the wrong frame; match the tool to your specific failure mix across retry logic, dunning, account updater, and gateway routing.
- Industry data puts transaction failure rates at 7.9% on average, with payment failures driving up to 40% of lost subscribers at high-volume businesses.
- Industry data shows smart retry systems observe 70 to 85% recovery on recoverable failures; fixed schedules land between 40 to 60%, with the gap coming from timing precision and decline classification.
- Require a concurrent holdout group, stratified randomization, and p-values before accepting any vendor benchmark; delta-based pricing signals a vendor confident in incremental lift.
- Slicker splits live traffic 50/50, measures dollars recovered against a concurrent control, and charges only on incremental recoveries above your existing baseline.
Why "Best" Is the Wrong Question for Failed Payment Recovery Software
Every "best failed payment recovery software" list ranks tools as if the problem were uniform. Pick the highest-rated option, install it, recover more revenue. The logic sounds clean, but it skips the question that actually matters: best for what gap, on which billing stack, proven how?
Failed payment recovery covers distinct disciplines. Smart retry timing, decline-code classification, dunning email sequencing, gateway routing, and account updater services each target a different failure mode. A tool that excels at retry timing may have weak dunning logic. Ranking them on a single axis produces a list that is technically accurate and practically useless.
The proof problem compounds this. Most vendor benchmarks are self-reported and measured against whatever baseline makes the uplift look largest. A buyer reading "recover 50% more revenue" has no way to know if that figure came from a controlled test or from comparing their worst historical month to the vendor's best customer.
A useful evaluation asks three things: what specific recovery layer is underperforming, does this vendor's approach match that gap, and how will they prove incremental lift on your own data before you commit?
What Failed Payment Recovery Software Actually Does
Recovery software sits between a failed charge and a lost subscriber, but what happens in that gap varies depending on which capabilities the tool actually runs.
The starting point is failure classification. Before any recovery action occurs, the system must determine whether a decline is recoverable. Soft declines like insufficient funds or network timeouts can be retried with the right timing. Hard declines like stolen cards or closed accounts require a different path entirely. Treating them the same wastes retry attempts and risks card network penalties.
From there, the functional paths diverge:
- Retry timing optimization: scheduling each attempt around issuer behavior, card type, and payday cycles instead of firing on a fixed calendar
- Account updater and tokenization: refreshing expired card details before a charge fails, through Visa Account Updater or Mastercard Automatic Billing Updater
- Dunning outreach: contacting subscribers when the failure requires their action, with messaging specific to the failure reason
- Gateway routing: directing retry attempts through the processor most likely to authorize based on historical performance
A tool built around dunning emails will not recover insufficient-funds failures that resolve with correct retry timing. A retry engine with no account updater misses a material share of expired-card failures before they even reach the retry queue. A shortlist built on category reputation instead of functional fit produces a tool that solves the wrong problem well.
The Four Functional Layers of Failed Payment Recovery
Most recovery tools bundle these capabilities without separating them. Knowing which layer you actually need changes the evaluation entirely.
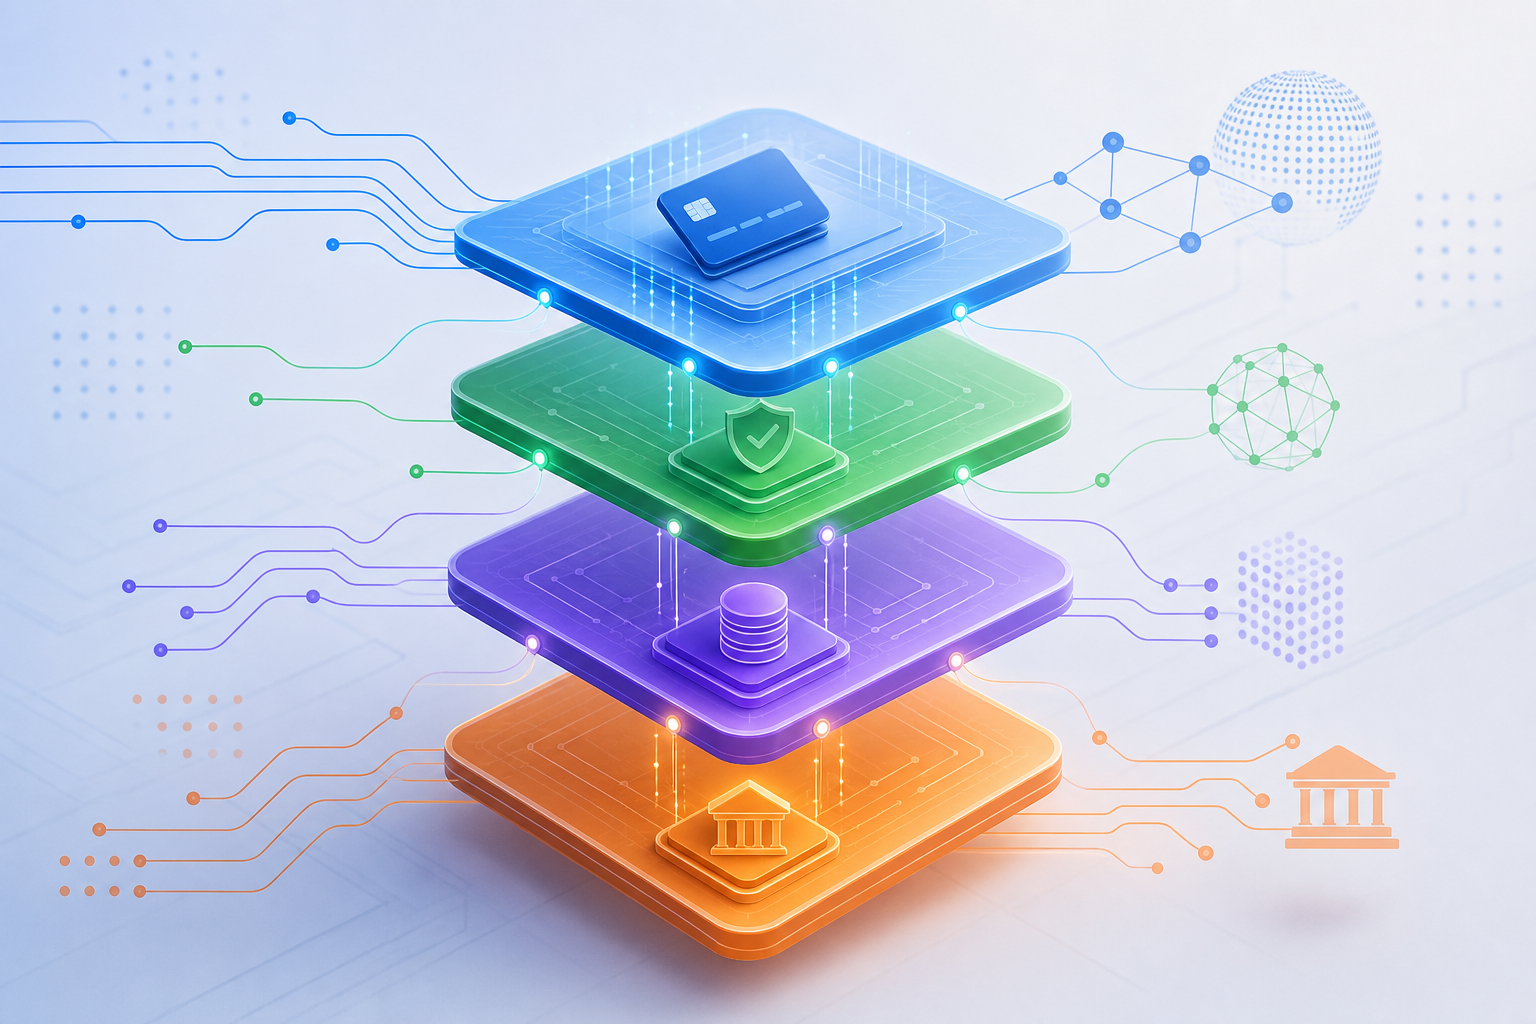
- Smart retry logic: decides whether to retry, when, and how often based on decline type, issuer behavior, card type, and geography. The core recovery engine for soft declines.
- Dunning communications: outreach sent only when customer action is required. Effective dunning is failure-specific, not a generic "update your card" sequence.
- Account updater and network tokenization: refreshes expired or replaced card details before a charge attempt fails. Visa Account Updater and Mastercard Automatic Billing Updater handle this at the network level.
- Multi-gateway routing: routes each retry through the processor with the highest historical authorization rate for that card type and region.
Vendors with deep retry logic often have shallow dunning, and vice versa. Buying a tool without mapping your failure mix to the right layer is the most common procurement mistake in this category.
Why Involuntary Churn Is a Revenue Problem, Not a Payments Problem
Voluntary churn leaves a signal: a cancellation click, a support ticket, an NPS dip. Involuntary churn leaves nothing. The subscriber intended to stay, the payment failed, and they disappeared without a complaint your retention team could act on.
That silence is what makes it dangerous at scale. The hidden cost of failed payments compounds quickly: industry data puts average transaction failure rates at roughly 7.9% across industries, reaching up to 14.7% in certain sectors, and payment failures account for as much as 40% of lost subscribers at high-volume subscription businesses. That is a revenue line CFOs should watch alongside voluntary cancellation rates.
The compounding effect matters too. A subscriber lost to a recoverable failed payment represents full CAC (customer acquisition cost) spent, no cancellation flag raised, and no retention intervention triggered. Every month the recovery gap stays open, the loss accumulates.
How Soft and Hard Declines Require Different Recovery Strategies
The decline code is where recovery starts or stops. Get the classification wrong and everything downstream fails.
Understanding soft vs hard declines is foundational: soft declines are temporary. Insufficient funds clear after a payroll deposit. Network timeouts resolve on their own. Temporary issuer blocks lift within hours. The right retry at the right time recovers these without the subscriber ever knowing there was a problem.
Hard declines are permanent without cardholder action. A stolen card will not authorize on the third retry. Retrying these burns attempts, triggers a Mastercard per-retry penalty when MAC Code 03 (Do Not Try Again) is present, and degrades your merchant ID (MID) reputation, lowering authorization rates on future first-time charges.
The real problem is the ambiguous middle. Codes like do_not_honor or generic_decline can be either soft or hard depending on the accompanying network code and Merchant Advice Code (MAC). A fixed retry schedule fires regardless. An intelligent classification engine reads the full signal set before acting, which is why classification accuracy is a prerequisite for recovery performance, not a feature.
What "Smart" Retry Logic Actually Means
Rule-based retry schedules fire on a calendar. Smart dunning and smart retry logic both read the transaction before deciding whether to act at all.
The signals genuine retry intelligence weighs include decline code, accompanying network code, card type, issuing bank behavior, geographic payday cadence, time of day, and any Merchant Advice Code (MAC) the network returns. Each variable changes the optimal recovery path. A consumer debit card in the US is most likely to authorize at 12:01am when payroll deposits clear. A UK subscriber on a monthly salary cycle has a different optimal window, typically within 48 hours of the last working day of the month.
Geographic payday patterns show where fixed schedules fail structurally:
- United States (biweekly pay): retry 2 to 3 days after the 1st or 15th, when payroll deposits are most likely to have cleared.
- Western Europe and UK (monthly pay): retry within 48 hours of month-end, then hold instead of firing again into an empty account.
- Australia (weekly or fortnightly pay): a 3 to 5 day retry interval after the initial decline catches most payroll cadences.
MACs add another layer. When a network returns a time-specific MAC, intelligent systems weigh that against the remaining dunning window. If the MAC says wait 10 days and the window closes in 5, the right answer is to retry before day 5, not follow the MAC and lose the subscriber entirely.
As an industry benchmark, smart retries consistently recover 70 to 85% of recoverable failed payments; fixed retry schedules typically land between 40 to 60%. These are observed industry figures, not guaranteed outcomes. The difference is not retry volume. It is timing precision and classification accuracy working together.
Native Platform Retries vs. Dedicated Recovery Tools
Billing platforms include retry logic because buyers expect it. That does not make it purpose-built for recovery.
Native solutions like Stripe Smart Retries or Chargebee's dunning apply fixed or lightly configurable schedules. They operate on one billing system's data and cannot learn from patterns across issuers, geographies, or card types observed elsewhere. Dunning emails in these systems are typically tied 1:1 to retry attempts, so every failed charge that triggers a retry also triggers an email, raising spam risk and subscriber fatigue with no independent cadence control.
The analytics gap is equally structural. Billing-native reporting tells you how many retries ran, rarely why specific failure types cluster by geography or issuer, or where recovery rate degradation is occurring.
Native tools are the right starting point at lower revenue volumes. Reviewing involuntary churn benchmarks by vertical helps clarify when the calculus changes as transaction volume grows: at scale, a 4 to 10 percentage-point recovery uplift represents material annual revenue, and the economics of a performance-based dedicated tool become straightforward. Native retry logic is a floor, not a ceiling. At enterprise scale, the gap between "adequate" and "optimized" is measured in recovered revenue your billing system leaves on the table each billing cycle.
Native Platform Retries (e.g. Stripe, Chargebee) | Dedicated Recovery Tool (e.g. Slicker) | |
|---|---|---|
Retry logic | Fixed or lightly configurable schedules | Intelligent scheduling across 40+ variables (card type, issuer, geography, payday cadence) |
Decline classification | Surface-level decline codes only | Full signal set: gateway code + network code + Merchant Advice Code (MAC) |
Dunning cadence | Tied 1:1 to retry attempts; no independent cadence control | Failure-specific outreach, decoupled from retry schedule |
Data scope | One billing system's data | Cross-issuer, cross-geography, cross-card-type pattern learning |
Recovery rate (recoverable failures) | 40 to 60% (fixed schedules) | 70 to 85% (smart retries with timing precision) |
Analytics | Retry counts; limited failure-type or geography breakdown | Segmented by decline type, geography, and issuer; concurrent holdout reporting |
Best fit | Lower revenue volumes; adequate starting point | Enterprise scale where a 4 to 10 pp uplift represents material annual revenue |
How to Vet Recovery Vendors Without Trusting Their Own Benchmarks
Vendor benchmarks have a structural problem: the vendor controls what gets measured.
Most published recovery rates reflect gross recoveries on a self-selected cohort, compared to a historical baseline chosen by the vendor. No concurrent holdout group. No stratified randomization. No way to separate the lift any tool actually produced from what your existing billing logic would have recovered anyway.
A credible evaluation requires four things:
- A concurrent holdout (control group): split live traffic simultaneously so both groups experience identical billing conditions, since historical comparisons conflate vendor performance with seasonal effects and billing cycle timing.
- Stratified randomization by failure type and amount: insufficient funds failures, generic declines, and expired cards recover at different rates, so skewing one cohort toward easier recoveries inflates numbers without any real performance advantage.
- Statistical significance reported as p-values and confidence intervals, not recovery rate percentages alone.
- Measurement in dollars recovered, not recovery rate: a tool recovering 80% of cherry-picked, high-probability failures may generate less incremental revenue than one recovering 60% of your actual failure mix.
When assessing subscription payment recovery platforms, delta-based pricing is worth reviewing alongside methodology. A vendor charging a percentage of all recovered revenue has an incentive to claim credit for recoveries your billing setup would have caught regardless. Delta-based pricing charges only on incremental recoveries above your existing baseline, so the vendor only wins when they produce genuine additionality. That structural alignment tells you more about a vendor's confidence in their results than any benchmark they publish.
Pricing Models and What They Signal About Vendor Incentives
Three pricing structures dominate this category, and each tells you something about what the vendor actually believes.
Flat monthly fees decouple vendor revenue from your recovery performance entirely. The vendor gets paid whether the tool produces meaningful lift or not. That works fine for analytics software; for a recovery tool, it removes the incentive to keep improving.
Percentage of all recovered revenue is more common but carries a hidden problem: if your billing infrastructure would have recovered 60% of retryable failures anyway, you're paying a share of work it did, not the vendor.
Delta-based pricing charges only on recoveries above your existing baseline, staking commercial terms on incremental lift. That structure is only viable if the vendor is confident in their performance.
One important caveat: at lower transaction volumes, the math does not always favor a dedicated tool. The commercial case scales with volume, which is why the strongest use cases sit at enterprise scale, where even a 4 to 10 percentage-point recovery uplift represents material annual revenue.
What Enterprise Buyers Should Require on Security and Compliance
Enterprise procurement treats a payment recovery vendor as a data subprocessor the moment it touches subscriber billing records. That classification triggers a compliance checklist most roundups never mention.
GDPR Article 28 requires a signed Data Processing Agreement (DPA) before any subprocessor handles personal data on your behalf. As Secure Privacy notes, a DPA is mandatory infrastructure for enterprise sales. Confirm it covers subprocessor liability chains and names any fourth-party processors the vendor routes data through.
Beyond the DPA, four requirements should be non-negotiable:
- SOC 2 Type 2 certification: confirms controls have been audited over time, not merely at a single point. SOC 2 Type 1 is insufficient for enterprise procurement.
- PCI architecture: a well-designed recovery vendor never stores or transmits raw card numbers. Payment credentials should stay inside your existing PCI-compliant infrastructure.
- Data deletion API: GDPR and CCPA both require the ability to delete subscriber personal data on request. Confirm the vendor exposes a deletion endpoint that propagates through their full data pipeline.
- Cyber insurance coverage: request a certificate of insurance with coverage appropriate to your transaction volume.
Slicker holds SOC 2 Type 2 compliance, is not PCI certified but is architected to avoid handling card credentials entirely, and offers a customer data deletion API. Payment credentials flow through your existing infrastructure; Slicker provides optimization intelligence only.
Key Metrics Revenue Operations Teams Should Track
Once a recovery tool is live, the measurement problem moves from vendor selection to performance management. Most teams track the wrong number first.
Initial failure rate is where monitoring starts, but final failure rate after the full dunning window closes is what matters. The gap between the two is your actual recovery. Track both by billing cycle so you can detect if your baseline failure rate is rising independently of recovery performance.
Five metrics worth building into regular reporting:
- Initial vs. final failure rate: the spread shows recovery contribution without crediting your billing system for what the vendor actually recovered.
- Recovery rate by decline type: insufficient funds, generic declines, and expired cards resolve at different rates. A failure reason dunning cadence routes each decline correctly; aggregate recovery rate masks which failure category is underperforming.
- Median time-to-recovery: days from initial failure to successful charge. A tool recovering the same percentage of failures three days faster reduces service disruption and content-access loss.
- Involuntary churn rate, reported separately from voluntary churn: conflating them makes retention interventions impossible to target correctly.
- MRR (monthly recurring revenue) impact: transaction count tells you volume; MRR impact tells you whether the right invoices are being recovered.
Week-over-week spikiness in recovery rates is usually an error mix problem, not a performance problem. Segmenting by decline type normalizes for that variance and separates genuine degradation from noise.
The Billing Stack Compatibility Question Every Buyer Gets Wrong
Most buyers assess recovery tools on features first and integration fit second. That order is backwards.
A recovery tool's performance ceiling is set by the data it can actually access. Billing system integration (Stripe, Chargebee, Recurly, Zuora, or Recharge) provides invoice state and subscription context. But network-level error codes and Merchant Advice Codes (MACs) live at the payment service provider (PSP) layer, which means Adyen, Checkout.com, Braintree, or Worldpay must also be connected directly.
Without PSP-level access, a recovery tool sees only the surface-level decline codes your billing dashboard shows. It cannot read the network code alongside the gateway code, cannot interpret MACs, and cannot distinguish a do_not_honor that warrants immediate retry from one that should trigger dunning instead. Retry timing built on incomplete signal data is a sophisticated-looking fixed schedule.
Confirm both integration layers are supported before any feature evaluation begins.
How Slicker Approaches the Evaluation Problem Differently
Slicker was built on a single premise: subscription businesses cannot trust vendor benchmarks, so the product proves performance on your data before you pay for it.
The mechanism is AABB testing in payment recovery, borrowed from clinical trial design. Live traffic splits 50/50 into a concurrent control group and a treatment group. Both experience identical billing conditions simultaneously. Recovery is measured in dollars, p-values are reported alongside confidence intervals, and if Slicker does not outperform with statistical significance, you do not pay. No historical baseline comparisons. No cherry-picked cohorts.
The pilot structure reflects the same logic: the first month is free, followed by three paid months with the option to cancel anytime, for a total 4-month pilot. Pricing runs 3 to 8% of recovered revenue, scaled to transaction volume. For businesses already recovering a share of failed payments through existing billing logic, a delta-based model charges only on incremental recoveries above that baseline, so commercial terms are tied to genuine additionality.
The retry engine weighs over 40 variables per transaction, including card type, issuing bank, BIN data, geographic payday cadence, and time-of-day signals down to the hour. A complete subscription payment retry strategy informs the full setup. Integration covers Stripe, Chargebee, Recurly, Zuora, and Recharge with a no-code setup that goes live in under five minutes. SOC 2 Type 2 compliance is in place, and payment credentials stay inside your existing infrastructure.
"Best" is not a list ranking. Best failed payment recovery software is provably best on your own transaction data, measured against a concurrent holdout, reported with statistical significance.
Final Thoughts on Picking the Right Failed Payment Recovery Software
Most buying decisions in this category go wrong at the first step: auditing features before confirming what failure type is actually driving the gap. Once you know your failure mix and which recovery layer is underperforming, the shortlist writes itself. Talk to us if you want a structured way to measure what your current setup is leaving on the table.
FAQs
How does AABB testing prove incremental ROI from a payment recovery vendor before you commit?
AABB testing splits live traffic 50/50 into a concurrent control group and a treatment group, both experiencing identical billing conditions simultaneously, so recovery is measured in dollars against a true holdout rather than a historical baseline the vendor selects. Statistical significance is reported as p-values and confidence intervals, not recovery rate percentages, which means you can see whether any lift is real or noise. Slicker runs this test during the first free month of its pilot: if Slicker does not outperform your existing system with statistical significance, you do not pay.
What payment recovery platforms work with Stripe, Adyen, and Braintree for subscription businesses?
Slicker integrates with Stripe, Adyen, Braintree, Checkout.com, PayPal, Worldpay, Cybersource, and Authorize.net at the payment service provider level, alongside billing systems including Stripe Billing, Chargebee, Recurly, Zuora, and Recharge. Both layers are required: the billing system provides invoice and subscription state, while the PSP connection surfaces network-level error codes and Merchant Advice Codes that billing dashboards do not expose. Without both integrations active, retry timing intelligence operates on incomplete signal data.
How does delta-based pricing differ from charging a percentage of all recovered revenue?
Unlike a percentage-of-all-recovered-revenue model, delta pricing isolates the vendor's actual contribution. See the pricing section above for full detail. Slicker offers both a standard recovered-revenue percentage model (typically 3 to 8% of recovered revenue, scaled to transaction volume) and a delta-based model for businesses that already recover a meaningful share of failed payments independently.
What metrics should a SaaS revenue operations team track to measure involuntary churn recovery?
Track initial failure rate and final failure rate after the full dunning window closes separately, since the gap between the two is your actual recovery contribution. Segment recovery rate by decline type (insufficient funds, generic declines, and expired cards) because aggregate recovery rate masks which failure category is underperforming and driving involuntary churn (payment-related subscriber loss, distinct from voluntary cancellation). Two additional metrics worth adding to regular reporting: median time-to-recovery in days, which measures how quickly subscribers return to good standing, and MRR (monthly recurring revenue) impact instead of transaction count, since transaction volume tells you activity while MRR tells you whether the right invoices are being recovered.
What causes week-on-week spikiness in payment recovery rates, and how should you track more consistent metrics?
Spiky week-over-week recovery rates are almost always an error mix problem, not a performance problem: if the proportion of easy-to-recover failures like insufficient funds moves relative to harder declines like generic errors, the aggregate recovery rate changes without any change in the underlying tool's performance. Segmenting recovery rate by decline type normalizes for that variance and separates genuine degradation from noise in your billing cycle. For businesses running Slicker, the analytics dashboard lets teams drill down by error code, payment method, and geography to distinguish a real trend from a change in the composition of failures arriving in a given week.
Related Articles
Decline Recovery Layers: Retries, Dunning & More (Sep 2026)
Most declined charges don't require a customer email. They need a well-timed retry, or a card number refresh before the attempt even fires. Dunning is the...

Expired Cards as a Churn Vector: The Plastic Aging Problem (Sep 2026)
A surprising share of lost subscribers didn't cancel. Their card aged out, the charge failed hard, and your billing system had no path forward. Separating...
Retry Velocity Limits: Issuer Caps Explained September 2026
When a retry velocity limit gets tripped, the damage shows up in two places: the per-attempt fees on transactions that were never going to convert, and the...
Stop losing revenue to failed payments
Join leading subscription businesses using Slicker to recover failed payments automatically.
Get Started